
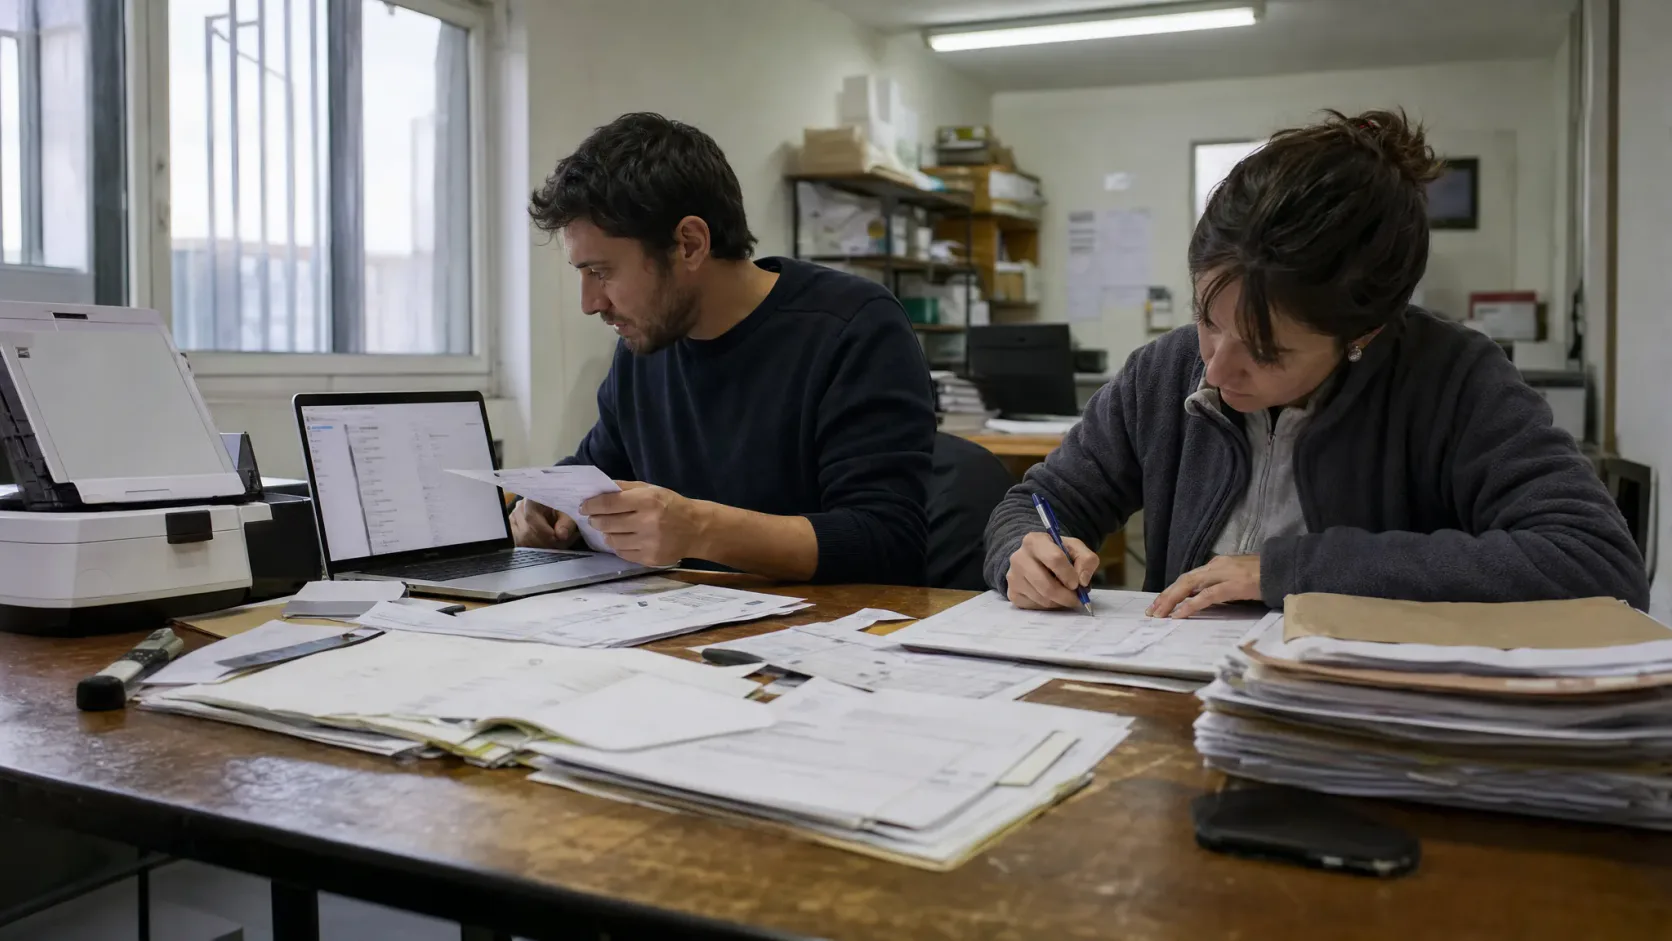
On Monday morning, one invoice arrives by email, another through a supplier portal, and a third comes with a delivery note that does not match the order. On the dashboard, everything looks tidy: documents received, process running, no open incidents. But on the accounts payable desk, someone is doing the opposite of what the dashboard suggests: copying data, comparing amounts, finding the right purchase order and calling purchasing to clarify one doubtful line.
The problem is not receiving more documents; it is deciding which error is cheap and which one is expensive.
My thesis is simple: automating invoices with AI is not about removing people, but about separating classification, extraction and validation according to the cost of error. When a company mixes those three steps, it creates a system that looks modern while simply moving work somewhere else.
The scene the KPI does not show
In many SMEs, the real invoice flow begins before the invoice itself. It starts when a supplier sends a file in a different format, when purchasing agrees to an exception, or when a warehouse operator confirms a partial delivery. Each of those actions leaves a different mark on the document, but the system usually asks for one answer only: approve or reject.
That is where friction between teams appears. Finance wants accuracy. Purchasing wants speed. Operations wants nobody to reopen what was already closed. The result is a loop of emails and small decisions that never appears on the dashboard because no one measures it as coordination cost.
AI helps when it reduces that invisible work. Not when it promises magic.
Three tasks, three risk levels
It helps to split the flow into three layers:
- Classify: know whether a document is an invoice, credit note, delivery note or receipt. Here some error can be acceptable if the follow-up review is cheap.
- Extract: read tax ID, invoice number, subtotal, VAT, due date, linked order and other fields. Here accuracy matters, but so does consistency: one bad field can break reconciliation.
- Validate: decide whether the document passes, gets blocked or needs human review. This is the most sensitive part because it affects cash and supplier relationships.
The key is to use different thresholds. It makes no sense to ask for human review on everything the model is 88% confident about if correction takes five seconds. It also makes no sense to let a small discrepancy pass on an invoice that could duplicate a payment or hide an incorrect charge.
OpenAI’s guidance on scaling AI is clear that successful adoption is not just about rollout; it is about building trust, governance and workflows where human oversight still makes sense. (openai.com)
The uncomfortable mistake: automating exceptions first
Here is the risky temptation. Many companies start with the loudest case: highly variable invoices, difficult suppliers or documents that “always cause trouble”. It feels logical because the pain is visible. In practice, it is often the worst place to begin.
Why? Because exceptions bring variety but little repetition. AI, especially at the beginning, learns better where there is pattern, volume and clear business rules. If you start with chaos, you can end up with an expensive tool that only creates more sophisticated manual review.
A composite example makes this easier to picture: a manufacturing company with centralized purchasing tried to automate all invoice intake at once. The project stalled because each department used different criteria for resolving discrepancies. When they split the flow into three groups — standard invoices, purchase-order invoices and invoices with discrepancies — adoption improved. Not because the AI changed, but because the business stopped asking it to make one decision for three different problems.
What leadership should measure before scaling
If you wanted to test this approach without launching a big programme, you would not just track the percentage of processed documents. You would look at more useful signals:
- how many invoices arrive without manual retyping;
- where human review stops and why;
- how long an exception takes to resolve from intake to closure;
- how often a supplier must resend the same document;
- how many exceptions are real business issues versus process noise.
That changes the conversation. You stop asking “is the AI accurate?” and start asking “what work does it remove, and what work does it shift?”. That is the difference between automation and hidden friction.
A small, reversible experiment
You do not need a large programme to learn. This week, you could try something smaller:
- take one document type, such as invoices from recurring suppliers;
- define three outcomes: automatic, human review and block;
- set different confidence thresholds for each critical field;
- manually review only a sample of the doubtful cases;
- measure how much time you save and which new errors appear.
If the experiment works, you will gain judgment. If it fails, you will have learned where the real cost sits without putting the whole operation at risk.
The question is not whether AI can read an invoice. The question is whether your company is ready to decide which review should remain human and which one is just feeding bureaucracy. What would you review less often if you could trust the first classification more?
At Codefuente, we usually start exactly there: where the real process and the dashboard tell different stories, because that is where automation stops being a promise and starts becoming operations.