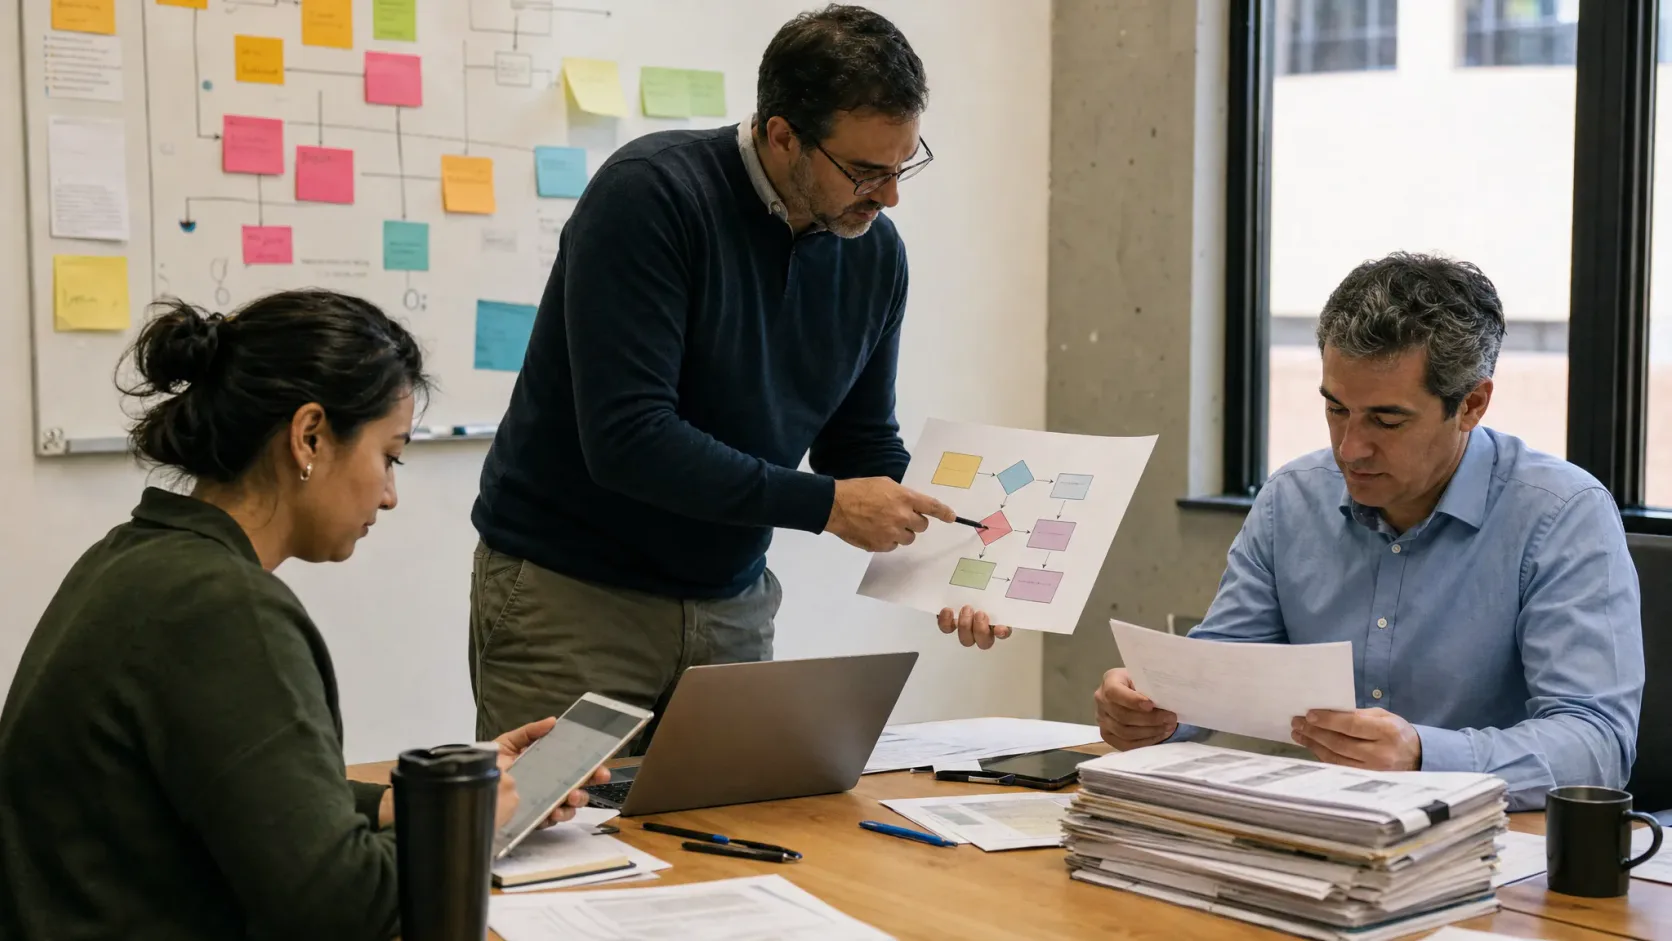
A company does not discover AI ethics in a lab. It discovers it on a Monday, when a customer complains, a candidate gets the wrong answer, or a team approves a decision no one actually reviewed.
The useful debate is not “use AI or not”, but “which decisions can it make alone, and which cannot”.
My view is blunt: in a serious business, AI should not decide on its own about people, money or access to services when the cost of error is high. It can speed things up, sort cases and suggest priorities. But if the decision has real impact, you need human review, documented criteria and a clear path to correction.
The realistic case that forces the issue
Imagine a 40-person services company. It wants to use AI to classify customer requests, prioritize incidents and pre-screen applicants. On paper, the idea looks sensible: faster response times, less manual work and better order. In practice, three uncomfortable questions appear.
The first is privacy. Which data actually enters the system? Do we need all of it, or are we feeding the tool information it would never need to make the decision? The second is bias: if the model learns from past decisions, it may copy old mistakes and package them as efficiency. The third is accountability: when a decision goes wrong, who answers, who reviews it and how is it corrected?
This is where business leaders need to separate legal obligation from good practice. The applicable law requires data protection, transparency and, depending on the use, specific obligations under the European AI framework. But a company can choose to be stricter than the legal minimum: for example, limit inputs, route uncertain cases to review and log why a recommendation was accepted or rejected.
Privacy: fewer inputs, better judgment
In most processes, the mistake is not “too much data” in the abstract. The mistake is not knowing what each field is for. If a classification can be done with request type and operational history, there is no reason to mix in sensitive fields or information that adds no decision value. Fewer inputs often means less exposure and less noise, not worse performance.
The practical question is simple: if someone asks to challenge a decision tomorrow, can we reconstruct what the system saw and why it produced that output? If the answer is no, the problem is traceability, not the model.
NIST’s AI Risk Management Framework is built around managing AI risk systematically across the lifecycle of the system, and its AI RMF 1.0 materials emphasize govern, map, measure and manage. The European Union’s AI Act is also already in force in its current timeline, with obligations that depend on the use case and risk level. In other words, companies should not treat AI like a harmless office app. (nist.gov)
Bias: the problem is not always the algorithm
Bias does not appear only because the model is “bad”. Very often it appears because the input data reflects past decisions, poorly recorded exceptions or criteria that were never consistent. If sales, support or HR already worked with uneven rules, AI can turn that inconsistency into speed, not improvement.
That is why three operational signals matter: systematic differences between comparable groups, cases the model scores with low confidence, and recurring errors at the same stage of the process. Without that measurement, we only have opinions. Opinions are expensive when the system scales.
Spain’s data protection authority has also made clear that AI does not remove privacy obligations or the need to examine bias linked to data quality. In plain terms: responsibility does not disappear just because a machine suggested the decision. (aepd.es)
The uncomfortable decision: let a real human intervene
Here is the hard part for many companies: human review cannot be decorative. It is not enough for someone to click approve after the system already steered the case. The reviewer needs time, context and real authority to change the outcome.
That changes process design. It may mean less full automation and more review queues. It may mean accepting slower handling for sensitive cases in order to avoid costly errors. It may also mean giving up the glossy promise of “fully automatic” in favor of something less flashy but far more defensible.
The useful measure is not how many cases pass through AI. It is how many are corrected, how many are explained and how many become complaints. If the system speeds up work but increases claims, the company has not gained efficiency; it has moved the problem elsewhere.
What to measure to know if it really works
Three metrics are enough to start without turning the project into bureaucracy:
- percentage of sensitive decisions reviewed by a person;
- rate of correction or reversal of AI recommendations;
- number of incidents, complaints or exceptions linked to the process.
From there, add one more question: can we audit a decision within a week, not a month? If yes, the system is becoming operable.
Three questions for this week
- Which decisions in your company should never be made by AI without review?
- Do you know what data each automated process uses today, and what data is unnecessary?
- Can your team explain a disputed decision with evidence, not instinct?
If your organization wants to use AI carefully, the goal is not to slow adoption down. It is to give it clear limits. At Codefuente, that is usually where the conversation should start: less hype, more judgment, and a process that survives an audit, a complaint and an ordinary Monday.