
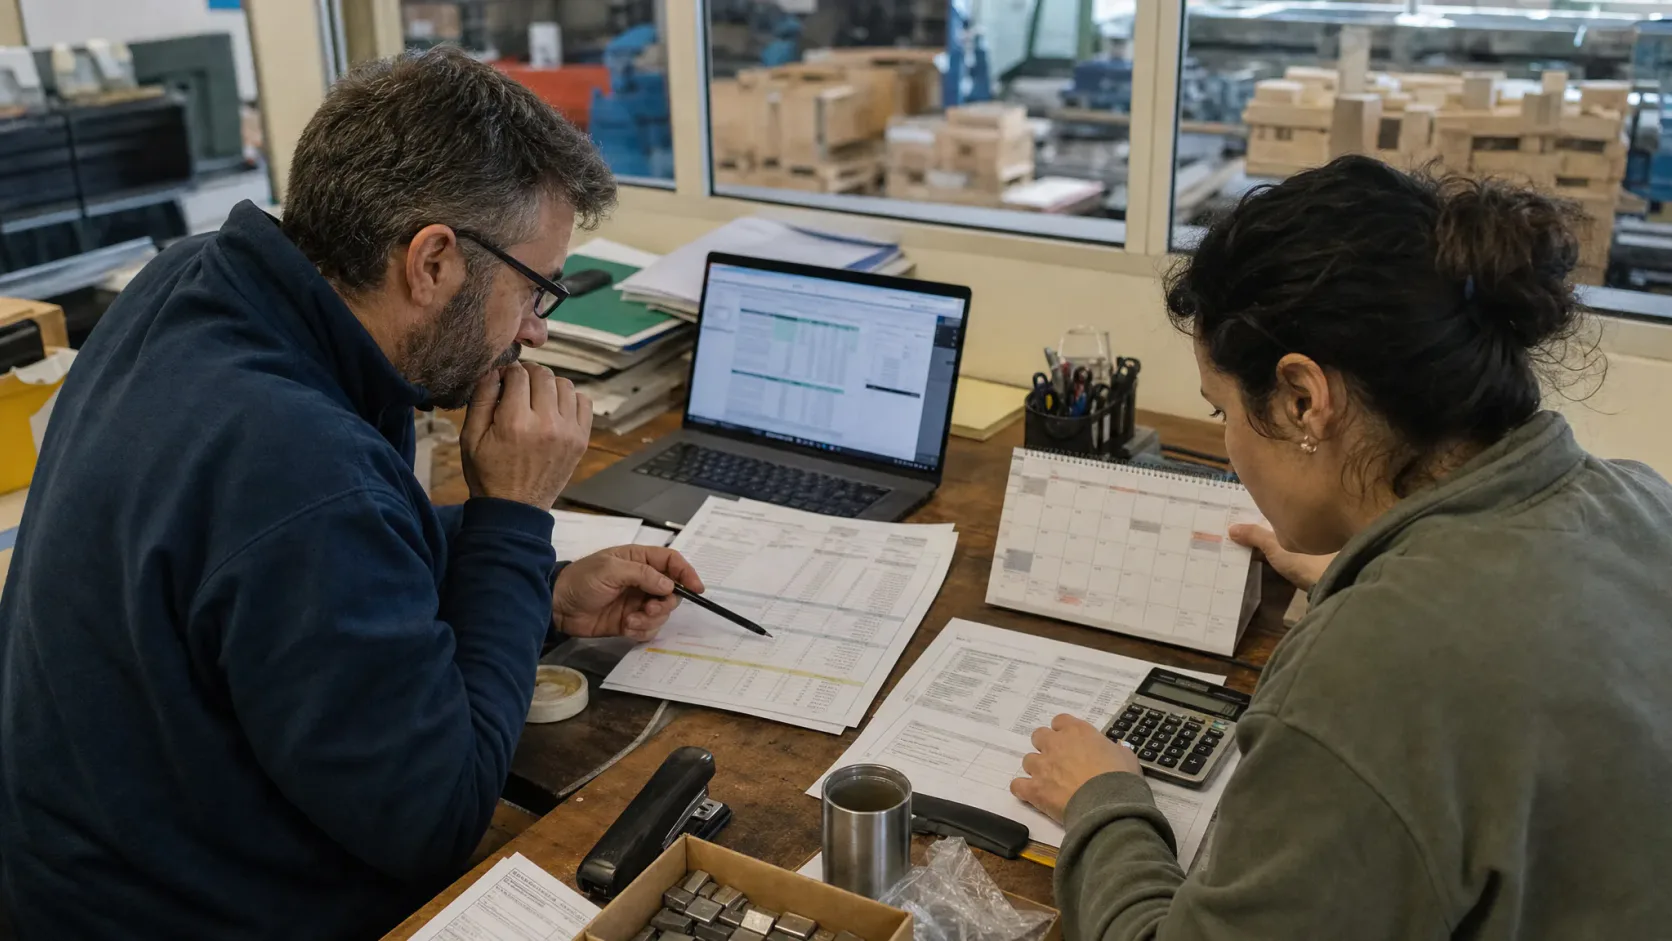
A purchase does not get delayed because money is missing. It gets delayed because nobody is comparing the same thing. That is the failure management dashboards usually hide: supplier A quotes per unit, supplier B per box, and supplier C around a minimum order; one includes freight, another invoices it separately; one gives ten business days, another two calendar weeks. On screen, everything looks tidy. In reality, the purchasing team is translating documents instead of making a decision.
The useful question is not whether AI can choose for you, but whether it can put every offer into the same language before anyone signs.
My thesis is straightforward: in traditional SME purchasing, AI is more valuable as a normalizer than as a decision-maker. If it first aligns units, lead times and terms, the comparison gets better; if it tries to recommend too early, it only polishes the noise.
The real bottleneck is not price
In many companies, purchasing, operations and warehouse do not look at the same thing. Purchasing wants to close fast. Operations wants to avoid stoppages. Warehouse wants to avoid filling the space with surplus material. Finance wants the invoice to match what was agreed. When each area protects its own metric, the result is manual reconciliation work.
A clear signal appears in behavior: emails asking “does this include freight?”, spreadsheets with last-minute columns, and decisions delayed because someone needs to “confirm the real delivery date.” That is not mainly a technology problem. It is a language-and-incentive problem.
AI can read offers and extract comparable fields: item, unit, quantity, net price, freight, taxes, lead time, validity, payment terms and penalties. But that extraction is not yet a decision. It is operational preprocessing.
What the process looks like step by step
A sensible SME flow would look like this:
- Input: offers received by email, PDF or Excel, plus the internal purchase request.
- AI task: read each document and propose a common table with normalized fields.
- Business rule: convert everything to the same reference unit and flag assumptions. For example, if a supplier sells by box, the comparison must show cost per unit, not only cost per box.
- Human approval: purchasing validates the relevant differences and operations confirms whether the lead time fits the real need.
- Measurable result: less comparison time, fewer transcription errors and more traceability about why one offer was chosen.
The key is to separate three things: AI interpretation, deterministic calculation and system integration. AI interprets text. The spreadsheet calculates. The ERP records the decision.
The uncomfortable mistake: asking AI to decide alone
Here is the uncomfortable part: if a company uses AI to approve purchases automatically, it is shifting risk without fixing the root cause. It may save time today and create a bad purchase tomorrow.
The most common risk is not a dramatic AI hallucination. It is a small normalization mistake: confusing business days with calendar days, missing a minimum order, or ignoring a short validity window. In purchasing, a small error can become stockouts, excess inventory or a production conflict.
NIST treats AI as a risk that must be managed throughout the lifecycle, with governance, mapping, measurement and management functions. It also stresses that risk management should be continuous and context-specific, not a mechanical checklist. (nist.gov)
A short scenario: three quotes, one useful comparison
Imagine a distributor buying packaging for several product lines. One quote looks cheap, but it is for a large box; another has a better lead time, but freight is separate; the third looks more expensive until everything is converted to unit cost and delivery is included.
Before, the team spent half a day rebuilding the comparison. After introducing an assistant that extracts fields and flags differences, the time drops because the team no longer starts from scattered documents but from a reviewed table. The decision still belongs to humans, but the discussion shifts from “what did each PDF say?” to “which option fits the operation best?” That small shift is highly valuable.
What to check before you scale it
You do not need a large AI program. You need a reversible experiment. For two or three weeks, measure three signals: time per quote comparison, number of recurring questions, and share of offers that need manual correction for unit or lead time.
If the pilot works, expand it. If it does not, you have lost little and learned where the noise is: in the input, in the rules, or in approval.
The best decision is not “automate purchasing,” but decide exactly which part of the job AI should do and which part must remain with people.
Three useful questions for this week:
- Which fields are you still comparing by hand in every quote, and which could be normalized?
- Where do errors appear most often: unit, lead time or payment terms?
- What small pilot could you test without changing final approval?
If useful, Codefuente can help you design that flow so AI reduces friction without removing control.